Oswin Data
Datasets for RAG, fine-tuning and training built from public sources
Oswin Data provides distilled web corpus datasets and AI-curated reference collections for machine learning teams. Includes 105B tokens of web documents, 15M
About this launch
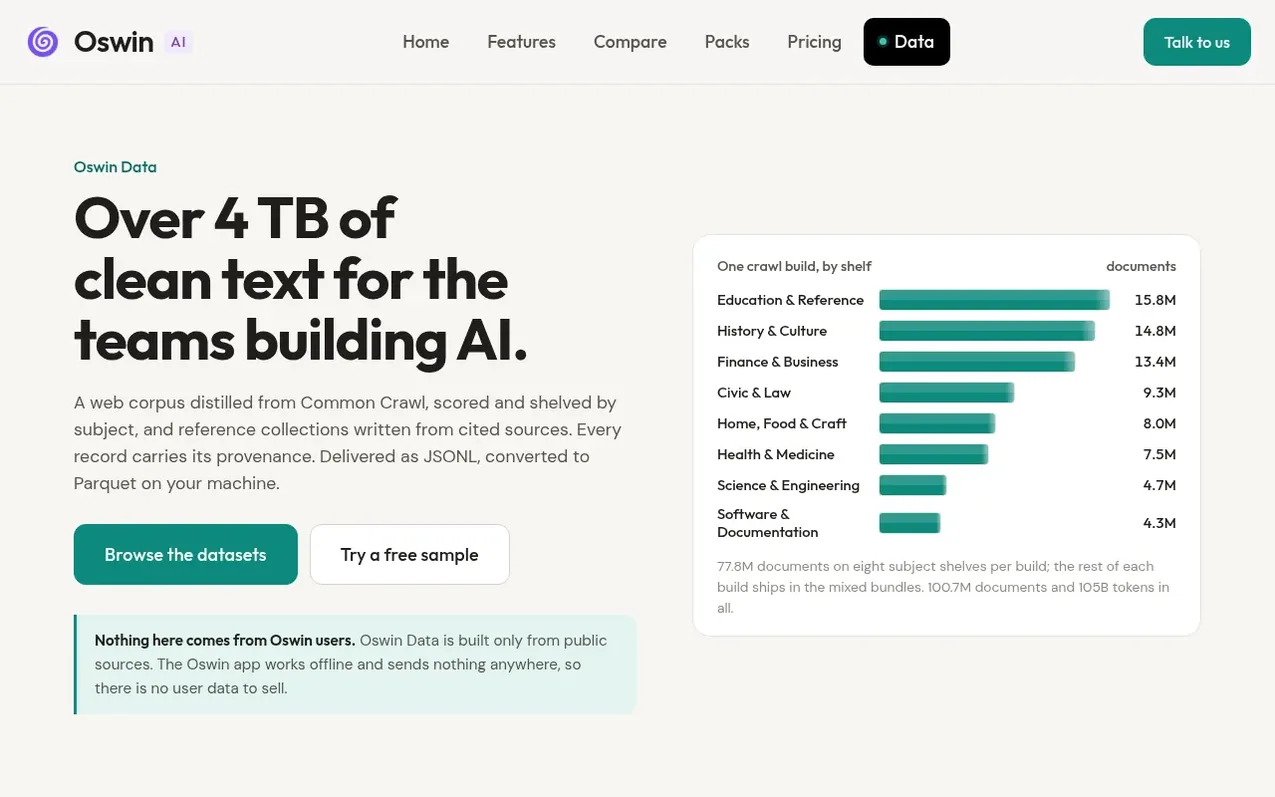
Oswin Data is a collection of datasets for machine learning teams. It includes a web corpus built from Common Crawl with 100.7M documents and 105B tokens per crawl, scored by domain quality and shelved by subject, plus five reference collections: 15M encyclopedia entries with cited sources, 200M question-and-answer records, 7,000 topics with statistics, 10,000 topics with glossaries, and long-form Q&A for 8,000 book titles. All records carry provenance and are delivered as JSONL and Parquet with free samples available. Nothing in the datasets comes from user data or proprietary sources.
What it does
- Web corpus with 100.7M documents and 105B tokens from Common Crawl
- Documents scored with Bear Rank and shelved by subject
- 15 million encyclopedia entries with sources and model attribution
- 200 million synthetic Q&A records with metadata
- Delivered as JSONL and Parquet formats
- Free samples available on Hugging Face
- Command-line client with resumable downloads and SHA-256 verification
- Statistics collection with 7,000 topics and 140,000 figures
- Glossaries for 10,000 topics with one million definitions
- Book Q&A dataset with 8,000 titles for reading comprehension
Pricing
Pricing model: Paid
Web Corpus: starter sets from $49 (250,000-500,000 documents); shelf corpora from $99-$199 per shelf (one-time license); Everything (full crawl) $3,000 one-time; Whole Library (all builds for one year) $5,000 per year. Reference Collections: Encyclopedia $1,200 commercial or $349 research (one-time)
Shopper questions
What is included in the web corpus?
The web corpus contains 100.7 million documents and 105 billion tokens from Common Crawl, cleaned through six gates (domain quality, safety, boilerplate removal, substance, de-duplication and labelling). Each document includes an exact token count, reading level, and Bear Rank score for the source domain.
What formats are the datasets delivered in?
Datasets are delivered as JSONL files, which can be converted to Parquet format on your machine using the provided command-line client. No account creation is required.
What licensing applies to the datasets?
Web corpus data is licenced for training, fine-tuning and evaluation. Reference collections use either CC BY-SA 4.0, CC BY 4.0, or commercial licences. Rights in original pages remain with their publishers.
Can I download free samples before purchasing?
Yes. Free samples are available on Hugging Face, including 10,000 web documents from every shelf, one million domain entries with Bear Rank scores, and 50,000 encyclopedia entries plus one million Q&A records from the reference collections.
How are the reference collections created?
Reference collections are written by language models from cited references, with each record naming its sources and the model that created it. Encyclopedia entries include summaries, children's versions, key facts, Q&A, glossaries and footnoted articles.
Oswin Data has a free listing. The owner can unlock the full profile with a paid launch for $5:
- Founder story (locked)
- Milestones (locked)
- Demo video (locked)
- Dofollow website link (locked)